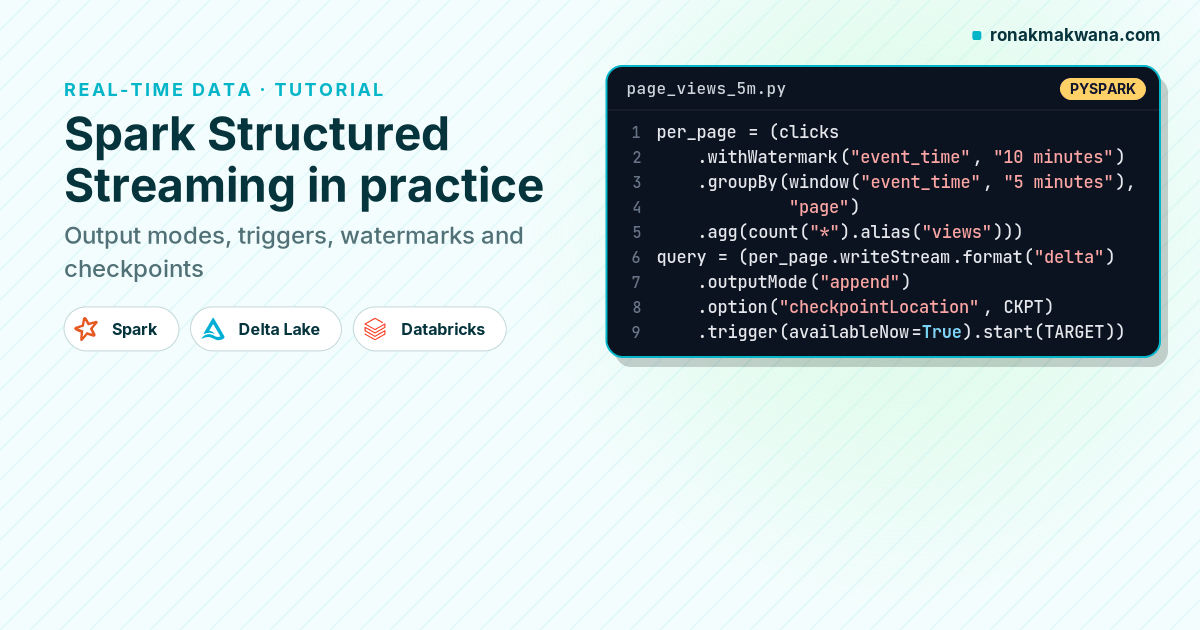
A hands-on guide to Spark Structured Streaming: the micro-batch model, sources and sinks, output modes, triggers, watermarks, foreachBatch upserts and monitoring, with output from a local run.
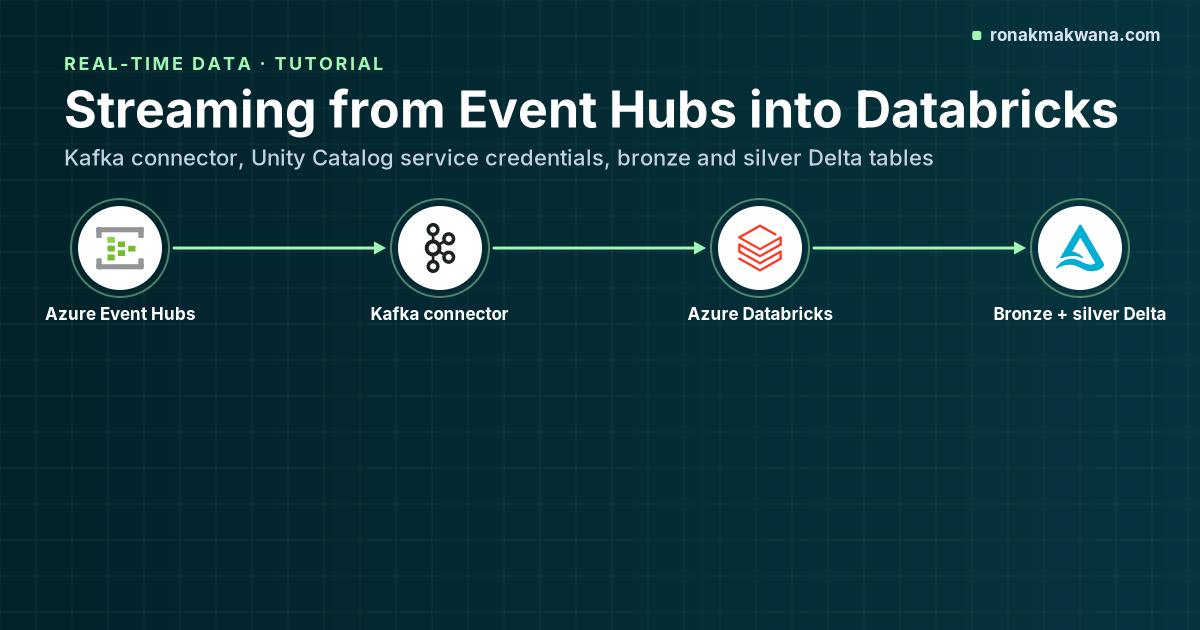
Step-by-step: stream Event Hubs events into bronze and silver Delta tables on Azure Databricks with the Kafka connector, a Unity Catalog service credential, watermarks and deduplication.
How Azure Event Hubs works under the hood: partitions and partition keys, sizing the partition count, consumer groups, checkpoints and tier limits, with Bicep and Python examples.
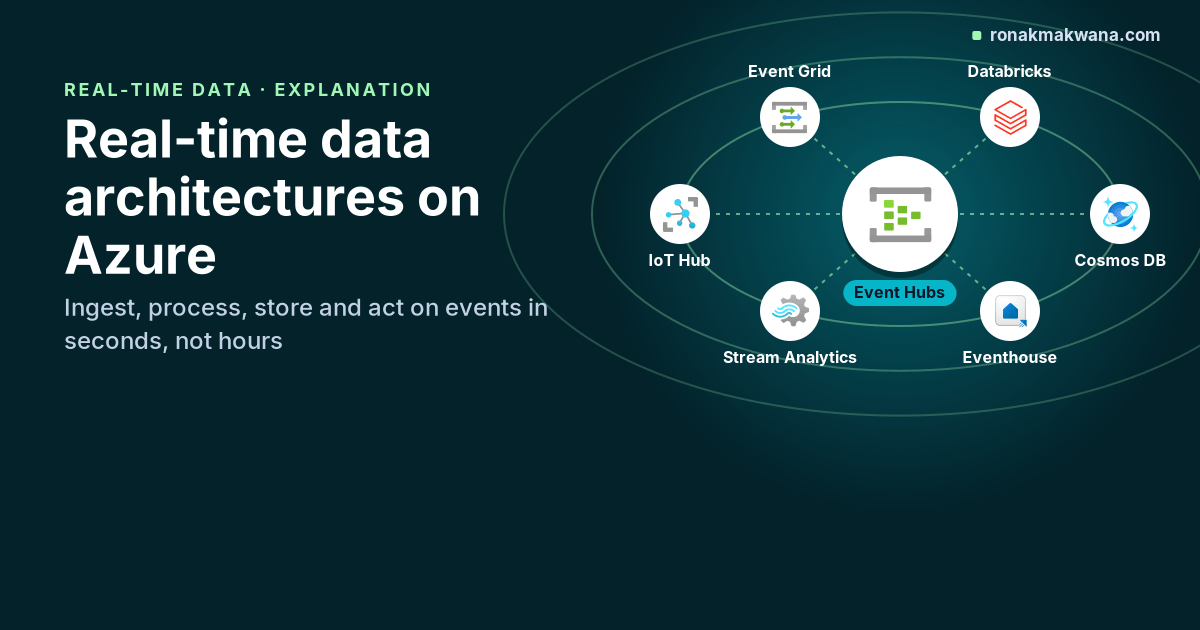
How to design a real-time data platform on Azure: latency tiers, Event Hubs ingestion, choosing Stream Analytics, Databricks, Fabric or Functions, and the decisions on event time, partitions and replay.
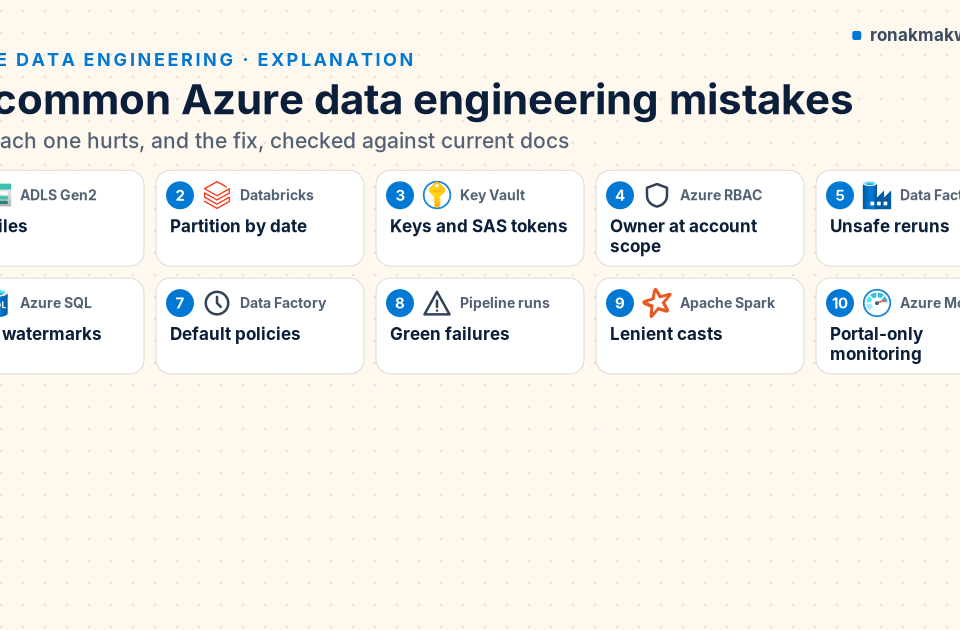
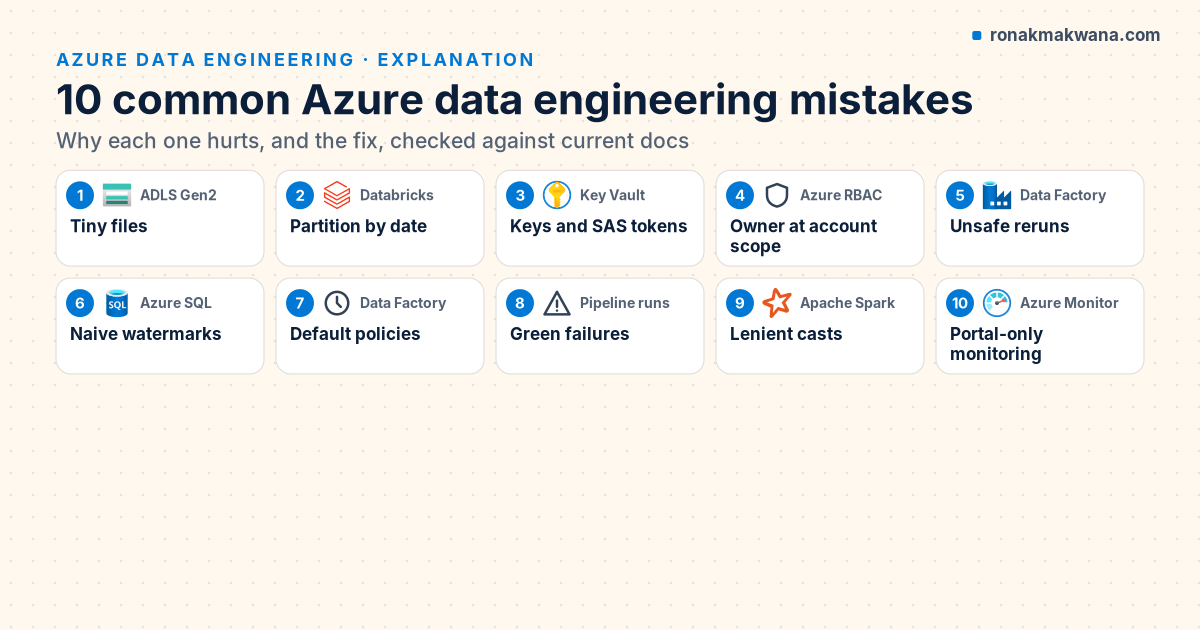
Ten mistakes that make Azure data platforms slow, insecure or unreliable, from tiny files and leaked keys to failure paths that report success, with the fix for each.
Remove secrets from Azure data pipelines: a user-assigned managed identity with least-privilege roles in Bicep, Entra-only SQL access, Key Vault for what's left, Databricks storage credentials, and audit logging.
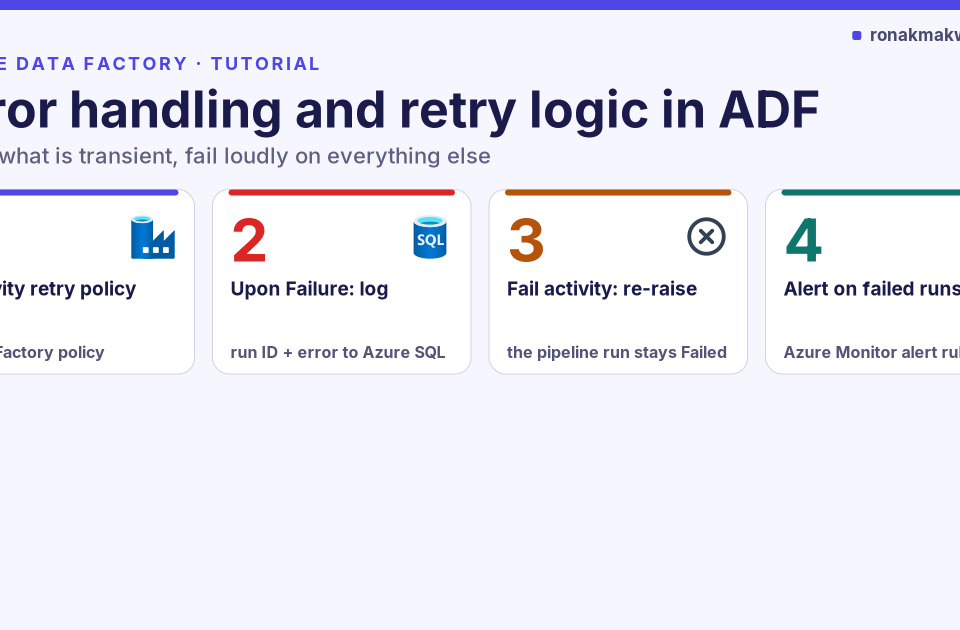
Layered error handling for Azure Data Factory: activity retries for transient faults, how pipeline success is really decided, log-then-fail handlers, Until/Wait polling, trigger retries and reruns.
Azure Data Factory and Azure Databricks overlap on ingestion, transformation and orchestration. Here's what each is built for, three common architectures, a decision guide and how their pricing differs.
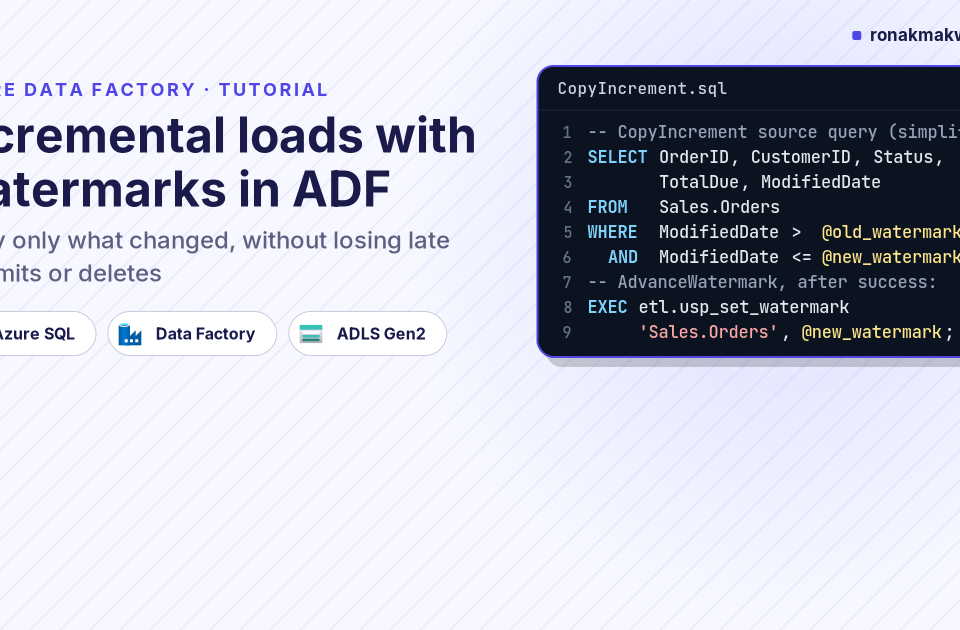
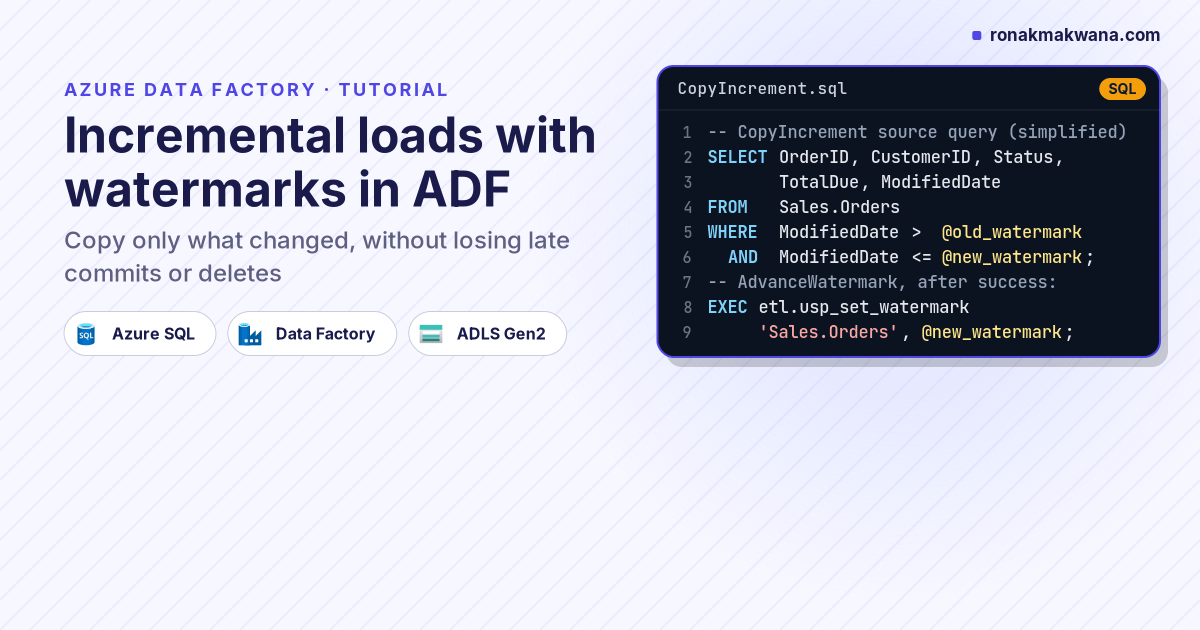
Build a watermark-based incremental load in Azure Data Factory, then close its two silent gaps: transactions that commit late and deleted rows, with overlap windows, rowversion and Change Tracking.