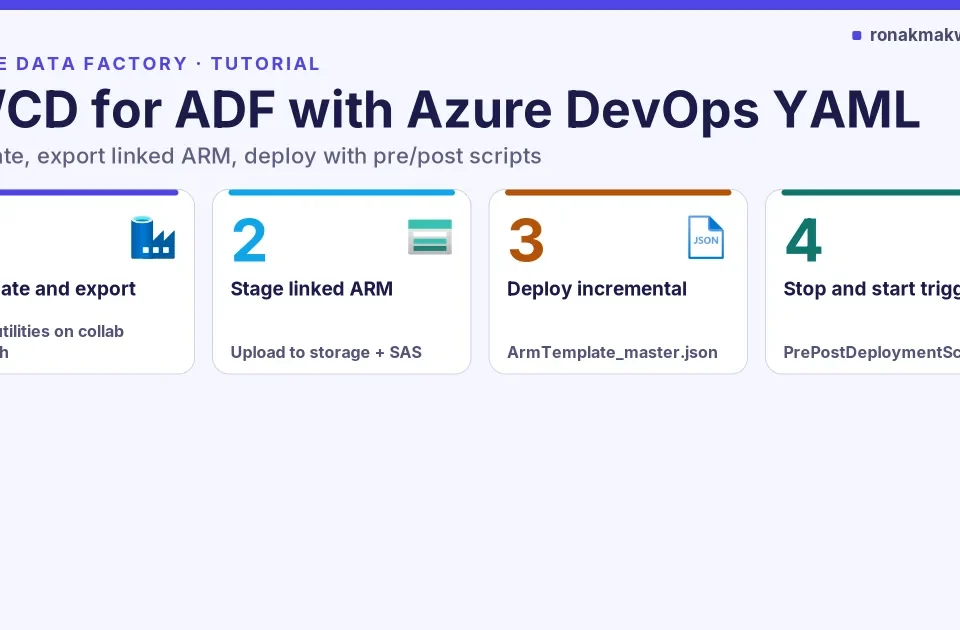
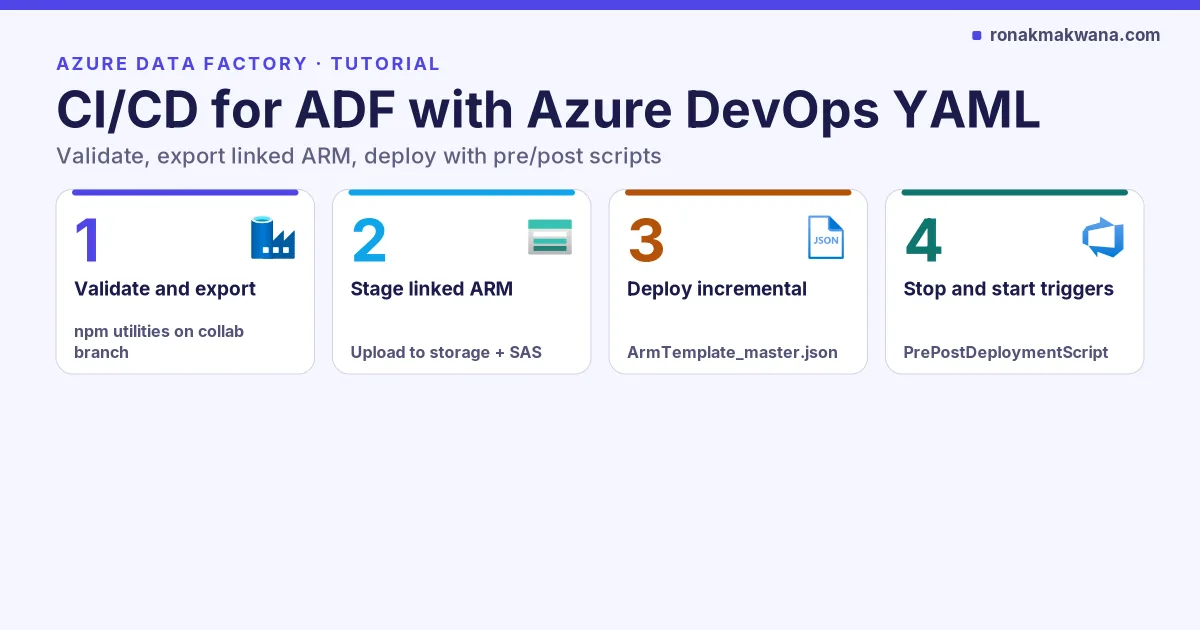
CI/CD for Azure Data Factory means promoting pipelines, datasets, linked services and triggers from a Git-backed development factory into test and production without clicking Publish in […]
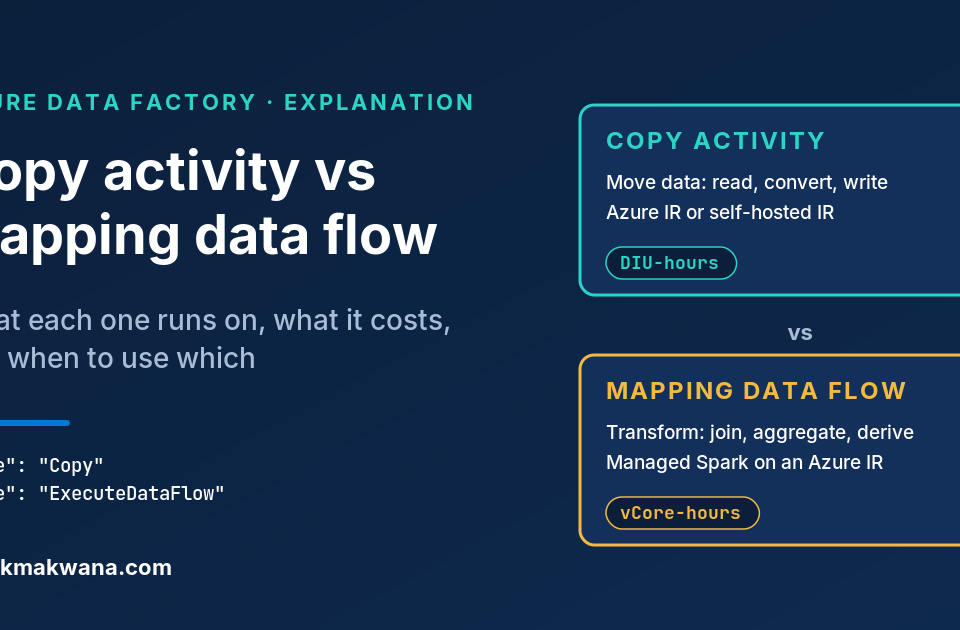
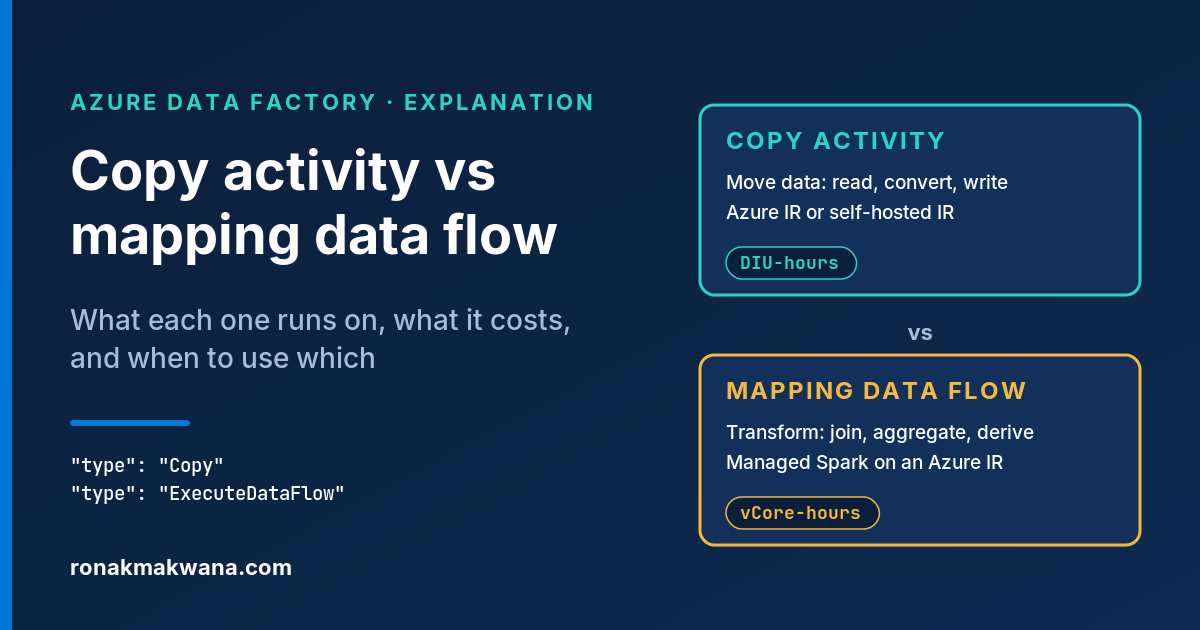
Copy activity moves data; mapping data flows transform it on managed Spark. How they differ on runtimes, connectors, transformations, tuning, billing, schema drift and debugging, how they combine, and a decision guide for choosing.
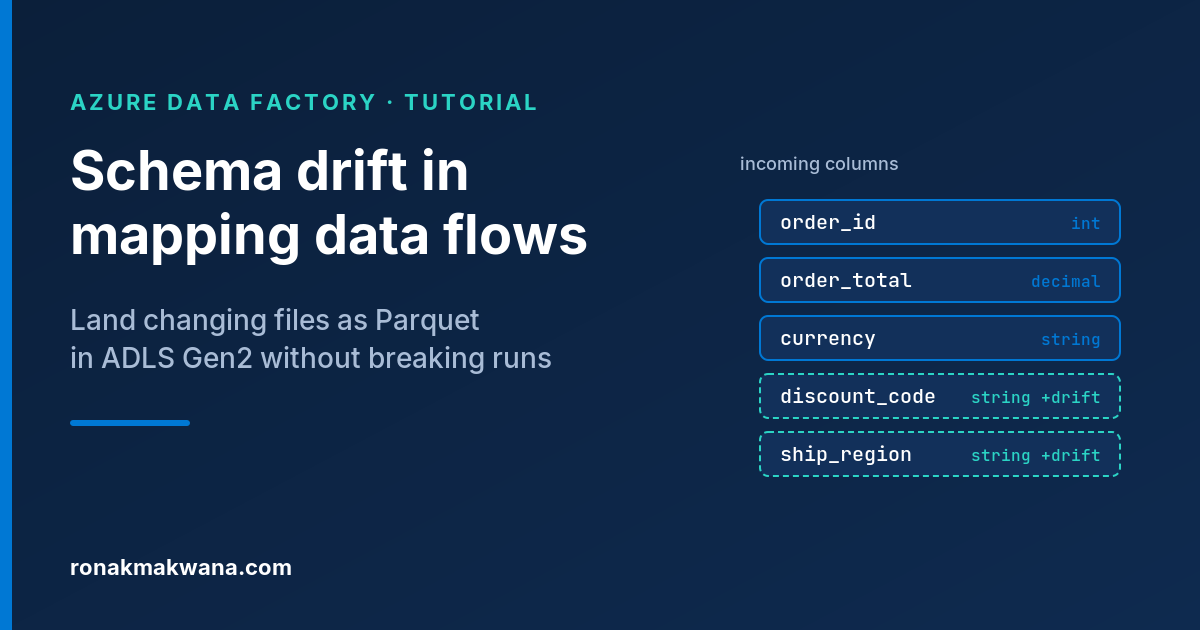
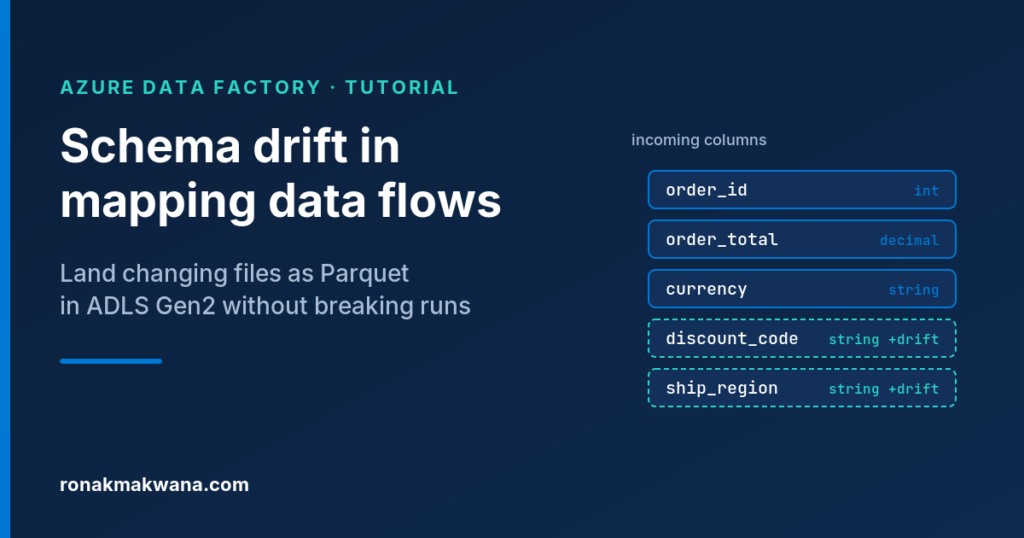
Make an Azure Data Factory mapping data flow survive new, renamed and retyped columns when landing Parquet in ADLS Gen2: source settings, byName(), column patterns, sink mapping and Parquet naming rules.
Layered error handling for Azure Data Factory: activity retries for transient faults, how pipeline success is really decided, log-then-fail handlers, Until/Wait polling, trigger retries and reruns.
Azure Data Factory and Azure Databricks overlap on ingestion, transformation and orchestration. Here's what each is built for, three common architectures, a decision guide and how their pricing differs.
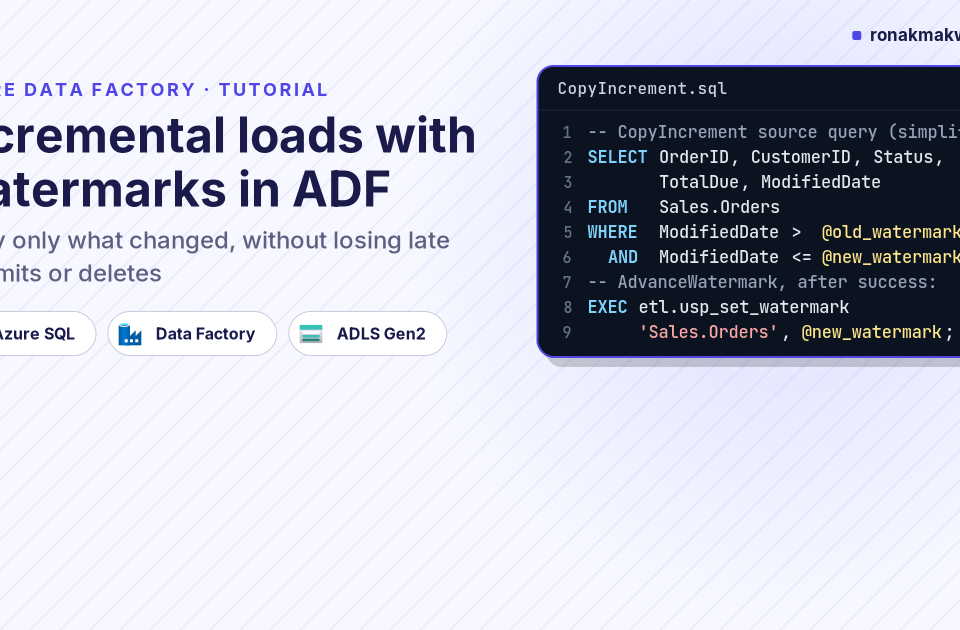
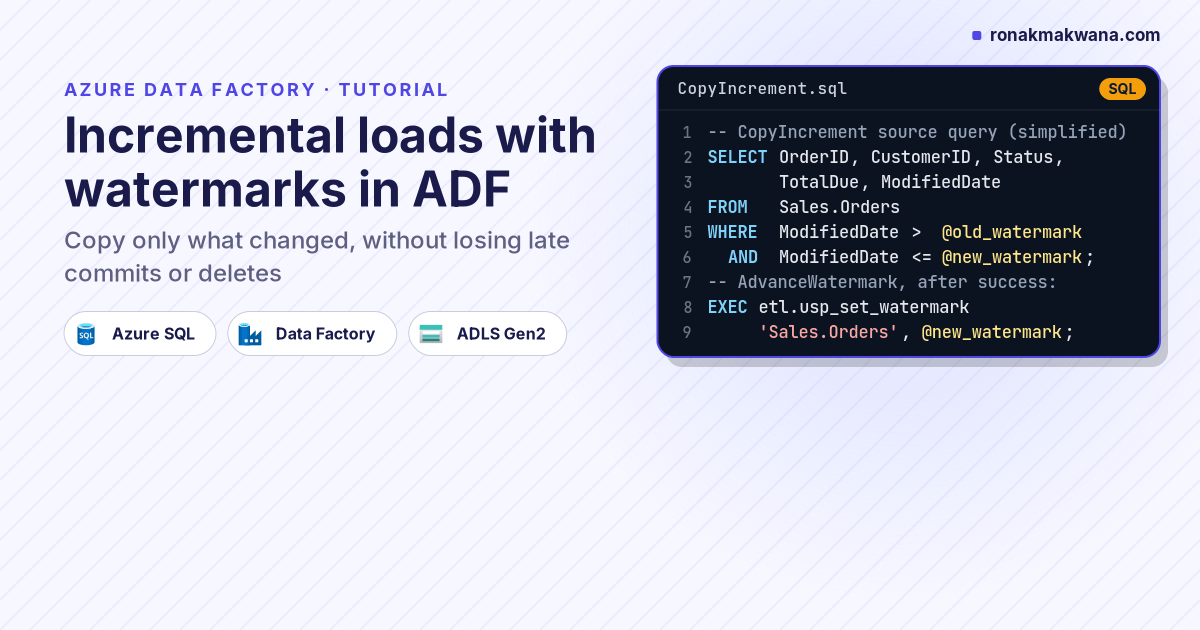
Build a watermark-based incremental load in Azure Data Factory, then close its two silent gaps: transactions that commit late and deleted rows, with overlap windows, rowversion and Change Tracking.
Build a metadata-driven Azure Data Factory pipeline: a control table in Azure SQL, Lookup and ForEach fan-out, a parameterised Copy activity landing Parquet in ADLS Gen2, and per-entity run logging.
A design guide for Azure Data Factory pipelines that survive production: orchestrator and worker pipelines, parameters, idempotent windows, timeouts and retries, concurrency, secrets, monitoring and CI/CD.